Self-supervised DINOv2 versus Supervised CNNs for Insurance Claim Cost Predictions
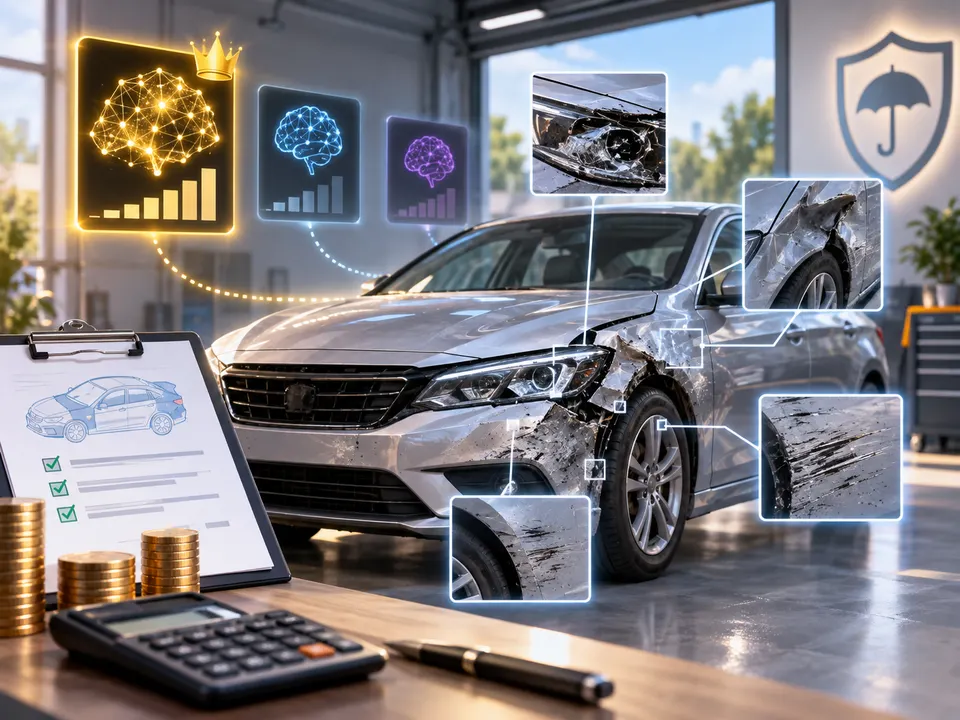
This study investigates whether vehicle insurance claim amounts can be predicted directly from images of damaged cars by comparing CNN models, the self-supervised DINOv2 model, and GPT-5.5 as a vision language model. Results showed that DINOv2 performed best, achieving an R² of 0.12 compared with 0.07 for ResNet152V2 and 0.08 for ResNeXt50, while GPT-5.5 tended to overestimate repair costs, particularly for severe damage.
Insurance companies handle millions of vehicle damage claims each year, creating a need for faster and more consistent ways to estimate repair costs. This study investigates whether insurance claim amounts can be predicted using only images of damaged cars. Three deep learning models were tested: ResNet152V2, ResNeXt50, and a self-supervised Vision Transformer called DINOv2 (small). All models used the same dataset of 1,337 vehicle damage images and training setup to ensure a fair comparison. Model performance was measured using mean squared error and R² score on normalised values. A quantitative comparison was also made using GPT-5.5 as a Vision Language Model (VLM) that used in-context prompting rather than task-specific fine-tuning. The results show that DINOv2 achieved the lowest error when compared to the Convolutional Neural Network (CNN) models. GPT’s estimates consistently overpredict costs, especially for severe damage. Overall, the findings suggest that the self-supervised DINOv2 features were more effective than the supervised CNN features tested here, with DINOv2-Small having achieved R² = 0.12 vs. 0.07 for ResNet152V2 and 0.08 for ResNeXt50.
Explore More!
Related Projects




© 2022 Inspirit AI. All Rights Reserved.