Back To Projects

Forecasting Bitcoin Price Direction from Twitter Sentiment and Market Data

Rishi N.

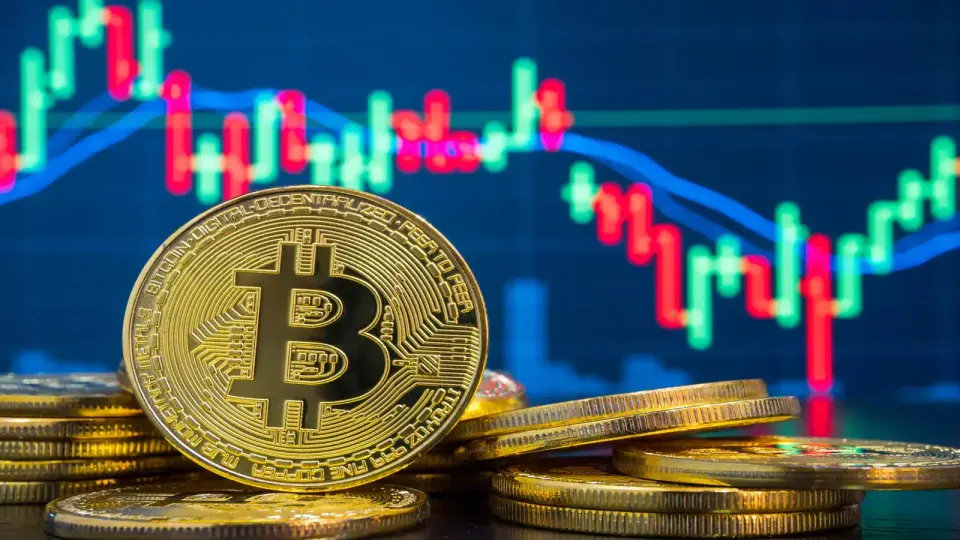
This research explores how social media sentiment affects cryptocurrency price movements using the 17.7 million Bitcoin Tweets dataset from Kaggle. By applying VADER sentiment analysis and training Random Forest and XGBoost models, the study achieved 74.15% accuracy, highlighting sentiment and market features as key predictors.


Forecasting Bitcoin Price Direction from Twitter Sentiment and Market Data, explores how social media emotions influence cryptocurrency prices. Using the 17.7 million Bitcoin Tweets dataset from Kaggle (2017–2019), I applied VADER sentiment analysis to link tweet tone with hourly market data. After cleaning, visualizing, and preprocessing the data, I trained two machine learning models—Random Forest and XGBoost—to predict Bitcoin’s price direction. XGBoost performed best, reaching 74.15% accuracy and showing that both market and sentiment features (like Compound Score and tweet volume) were key predictors. Future plans include feature engineering, hyperparameter tuning, and combining models for improved accuracy.

Explore More!
Rishi N.
John Basbagill

Related Projects

Using Neural Networks to Predict U.S. Corporate Profits on Electronic Goods

The goal of this project is to train two neural network AI models: a Multi-Layer Perceptron (MLP) neural network and a Long Short-Term Memory (LSTM) neural network, to predict U.S. corporate profits on electronic goods into the future.
Will K.
Mentored by Ana Sofia Muñoz Valadez
Predicting the Price of New York City Airbnbs

How can one predict the price of a New York City Airbnb? We are trying to create a machine learning model that can predict the price of a NYC Airbnb given some factors with high accuracy.
Bobby B.
Mentored by Tomer Arnon
Approaches to fraud detection on credit card transactions using artificial intelligence methods

In this paper, we study the problem of detecting fraudulent credit card transactions. We select the most relevant features using a heuristic approach, and fit three different model classes to a simulated dataset: Logistic Regression, Random Forests and Gradient Boosting Machines. We find that hyperparameter tuning has a big impact on the precision and recall of our classifiers. We also find that of the three classes, Gradient Boosting Machines were the best-performing model class, achieving 83% precision and 64% recall on unseen data.
Aryaman R.
Mentored by Yuan Lee