Back To Projects

Predicting the Price of New York City Airbnbs

Bobby B.

How can one predict the price of a New York City Airbnb? We are trying to create a machine learning model that can predict the price of a NYC Airbnb given some factors with high accuracy.


How can one predict the price of a New York City Airbnb? We are trying to create a machine learning model that can predict the price of a NYC Airbnb given some factors with high accuracy. There are many factors that contribute to pricing an Airbnb. This model is important because it can help people list their Airbnb for a fair price and help a renter determine if a listing price is fair. We first found a dataset containing the price of New York City Airbnbs and many features about these houses. This dataset also contained many factors about the houses that could be important for predicting prices. We then condensed the data into only the data that we thought were important. We compared several regression models to see which would predict the price best. The random forest regressor predicted the price with about 27% away from the price on average. The SGD regression predicted the price with an error of about 42%. Our model wasn’t very accurate when predicting the price. To accurately predict the price, more factors about the housing are most likely needed. Some of these could be square footage, bathrooms, and bedrooms. Though, these weren’t on the dataset we used.

Explore More!
Bobby B.
Tomer Arnon
MS Engineering at Stanford

Related Projects

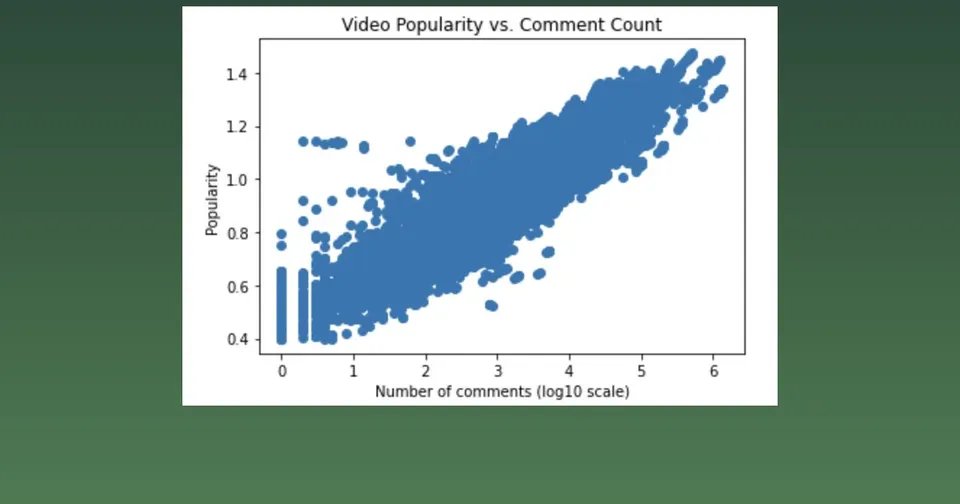
Analysis of Trending YouTube Videos: Finding Patterns in Viral Content

As the digital world continues to grow, content creators frequently have trouble building a community and producing videos that will interest their audience. Especially as these people look toward the internet for both recreational and monetary reasons, finding out techniques to build a community is important in today’s age. This paper analyzes the issues of video performance, revealing the patterns of what makes a video successful and viral. By training different models and testing different datasets, we were able to find the correlation between the potential chances of popularity and the video’s content. Using the most accurate model, the Random Forest model, content creators can see whether or not they are likely to do well based on patterns found in trending videos.
Vincent P.
Mentored by Amanda Wang
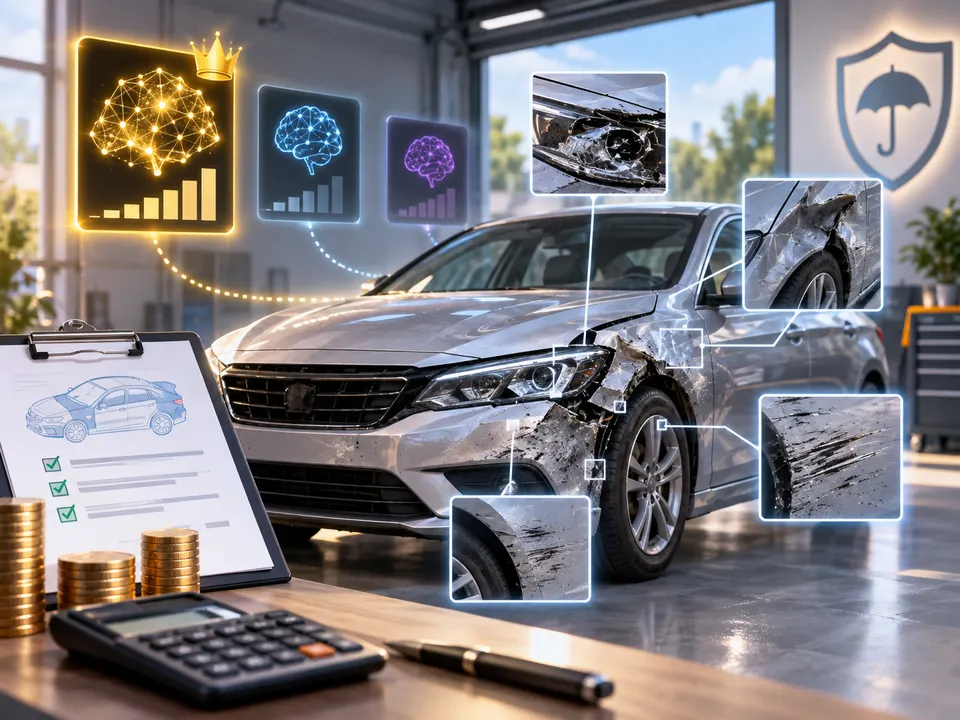
Self-supervised DINOv2 versus Supervised CNNs for Insurance Claim Cost Predictions

This study investigates whether vehicle insurance claim amounts can be predicted directly from images of damaged cars by comparing CNN models, the self-supervised DINOv2 model, and GPT-5.5 as a vision language model. Results showed that DINOv2 performed best, achieving an R² of 0.12 compared with 0.07 for ResNet152V2 and 0.08 for ResNeXt50, while GPT-5.5 tended to overestimate repair costs, particularly for severe damage.
Rohan V.
Mentored by Ivan Felipe Rodriguez
Forecasting Bitcoin Price Direction from Twitter Sentiment and Market Data

This research explores how social media sentiment affects cryptocurrency price movements using the 17.7 million Bitcoin Tweets dataset from Kaggle. By applying VADER sentiment analysis and training Random Forest and XGBoost models, the study achieved 74.15% accuracy, highlighting sentiment and market features as key predictors.
Rishi N.
Mentored by John Basbagill