Back To Projects

Modeling Sleep Efficiency

Nimeesha K.

This study explores how alcohol use, exercise, and smoking affect sleep quality by analyzing a dataset containing various lifestyle and sleep-related factors. Using a regression-based predictive model, the research identifies relationships between these behaviors and sleep outcomes, with the final linear regression model achieving a mean absolute error of 0.051.


I’ve always been interested in sleep and why some people tend to sleep better than others. I think it’s important to recognize what could be affecting a person’s sleep and what they can do to improve it. The goal of my research question, “How much do alcohol, exercise, and smoking affect sleep?” is to show how factors such as these can affect the quality of one’s sleep. I found a data set consisting of many factors that can affect sleep, as well as sleep quality. Using this data set, I built a model that allows you to input values for factors and come out with a sleep quality score. My model is a regression model, as it makes predictions through numerical data given to it. I tested out different models, settling on the most accurate one, Linear Regression, with a mean absolute error of 0.051.

Explore More!
Nimeesha K.
Serena Hughes

Related Projects

Individualizing Medicine: AI in Predicting the Effect of Yoga on Adrenomedullin Levels

I created and tuned four regression models that predicted a patient’s ADM levels after doing yoga: a Linear regressor, a Random Forest regressor, a Ridge regressor, and an Artificial Neural Network(ANN).
Smriti R.
Mentored by Varsha Sandadi
Optimizing Predictive Models for Healthcare: A Comparison of Personal and General Datasets in Coronary Artery Disease Risk Assessment

This research investigates how the choice of training population, personalized versus more general datasets, impacts the performance and generalizability of machine learning models for predicting Coronary Artery Disease risk. By comparing models trained on datasets of varying specificity using data from the UC Irvine Machine Learning Repository, the study explores trade offs between accuracy and broad applicability to improve strategies for early CAD risk assessment and prevention.
Isaac G.
Mentored by Raphi Kang
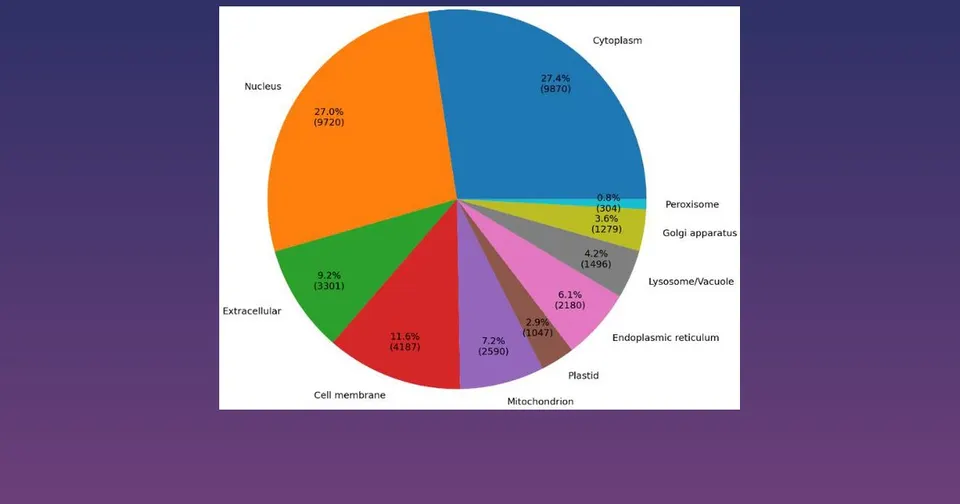
Multi-Label Prediction of Protein Subcellular Localizations through Machine Learning and State-of-the-art Structural Embeddings

This research explores various machine learning models to predict protein subcellular localization using UniProt’s Swiss-Prot database and Meta’s high-performing ESM2 structural embeddings.
Alfred B.
Mentored by Ayush Pandit